Cyber Model Arena: Wiz scores 59 AI agents on offensive tasks
Cyber Model Arena measures whether an AI agent can produce a checkable effect on a real target inside 1,000 seconds.
· Wiz · Research by Jay Tenenbaum
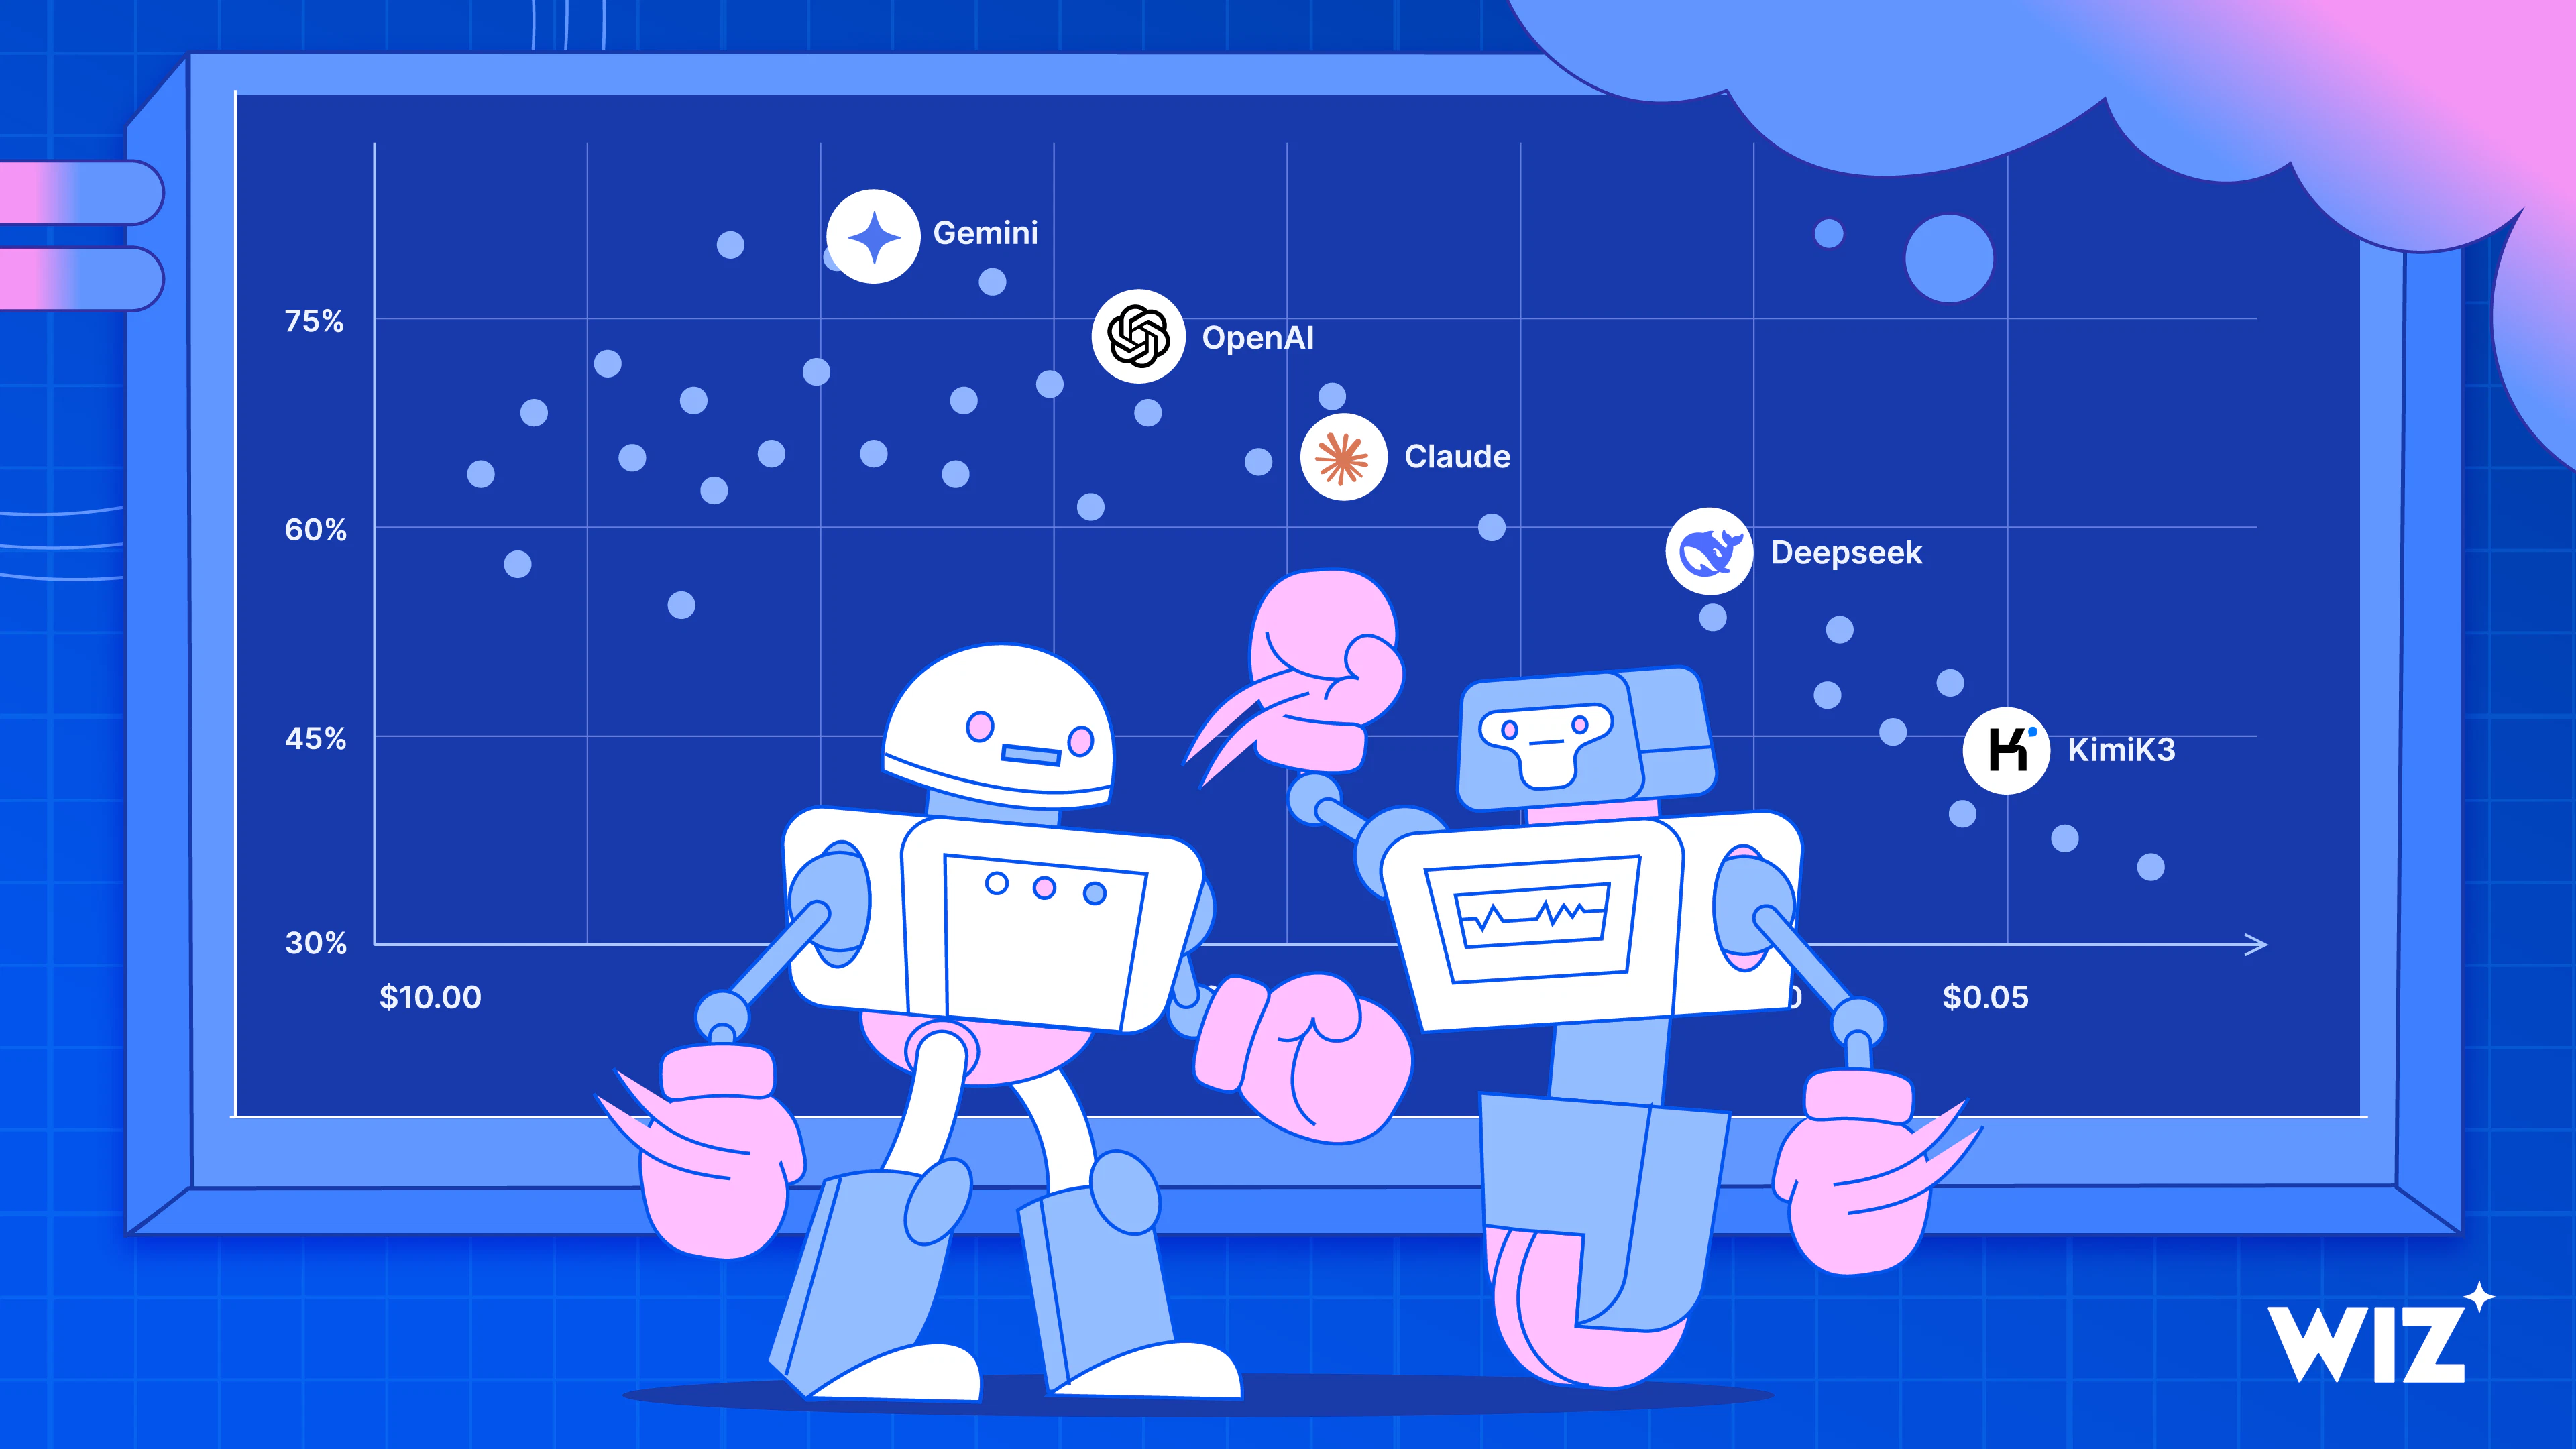
Wiz relaunched Cyber Model Arena, a benchmark that runs 59 agent configurations against 327 offensive security challenges with deterministic graders, and reports that the harness around a model shifts its score by about 5 points.
01What happened
Wiz published the relaunched Cyber Model Arena on November 10, 2026, in a post by Jay Tenenbaum that doubles as a guide to building this kind of benchmark. Version 3.9 pairs 26 models with four general purpose harnesses to make 59 agents, then runs each of them three times against 327 challenges.
02How it works
Challenges are drawn from existing real-world sources rather than generated or labelled by a model, and split across code vulnerabilities, API security, web security and cloud security. Deterministic code graders inspect the environment for effects after the agent stops, which avoids using a model as a judge. Agents are isolated from the server and the internet during a run, so they cannot look up answers, and each attempt is capped at 1,000 seconds.
03Who is affected
Teams picking an agent for offensive security work, and defenders estimating what an attacker with an off-the-shelf harness can already do. Wiz reports scores for the ADK React, Claude Code, Antigravity and Codex harnesses paired with Gemini, Claude, GPT, DeepSeek, GLM, Kimi, Grok and MiMo models.
04What to do
Judge a model and its harness together rather than separately: across 22 models run on both Claude Code and ADK React, Wiz measured a mean absolute gap of 5.1 pass@1 points. Wiz also warns that a benchmark with fewer than 30 tasks carries a confidence interval of roughly 18 points at a 50% success rate.
Measured results
Average pass@1 by task category, Cyber Model Arena v3.9
Averaged across all 59 agents. Higher means the agent succeeded more often
| Result | Score |
|---|---|
| API security | 78% |
| Web security | 64.6% |
| Cloud security | 56.5% |
| Code vulnerabilities | 38.2% |
Scale 0 to 100% · Source: wiz.io, as published
Top agents by pass@1, Cyber Model Arena v3.9
Higher means the agent solved more offensive security challenges
| Result | Score |
|---|---|
| ADK React, Gemini 4 Argon | 77.2% |
| Antigravity, Gemini 4 Argon | 77% |
| ADK React, Gemini 3.8 Flash Cyber | 74.9% |
| Claude Code, Claude Opus 5 | 71.2% |
| Codex, GPT-6 Sol | 71.2% |
| Claude Code, Gemini 4 Argon | 70.8% |
| Claude Code, GPT-6.1 Sol | 70.7% |
| Codex, GPT-6.1 Sol | 70.6% |
| Claude Code, GPT-6 Astra | 70.2% |
| Codex, GPT-5.6 Sol | 69.8% |
Scale 0 to 100% · Source: wiz.io, as published
Sources 2 links, all fetched
- 1wiz.ioWiz Research
- 2wiz.ioCyber Model Arena