Category
Attack
New prompt injection, jailbreak or agent attack techniques.
Incident feed
77 of 77 · newest first GPT-5.2PuzzleMask: a weak LLM guard misses what the strong model runsPuzzleMask hides a policy-violating payload in a wrapper that a lightweight LLM screen cannot read, while the stronger model behind it still acts on the payload. Check Point Research reports the technique worked on GPT-5.2-thinking-high.
 AgentDojoAutoPI: a red teamer that counts how many ways an agent breaksAutoPI is an adaptive prompt-injection red teamer that writes one injection per technique in the PIAtlas taxonomy and reports technique coverage alongside attack success rate. The authors evaluate it on AgentDojo and IPI Arena.
 Hermes
 Silent Lynx: an exposed server shows an AI agent running the intrusionSilent Lynx ran an espionage campaign against Tajik government networks using Hermes, an open-source agent framework, after CloudSEK found the operator's unauthenticated server holding more than a dozen gigabytes of tooling and victim data.
 GitHub Copilot CLIDevice code phishing: an approved code reaches a Copilot CLI sessionMicrosoft Security Research shows that device code phishing aimed at GitHub Copilot CLI, rather than at a mailbox, can let an attacker steer a running agent session, poison its memory, read synced sessions and reach private repositories.
 WordPressexploit_agent: patch to exploit with no human in the loopexploit_agent is a multi-agent framework that compares software before and after a patch, works out the flaw, writes an exploit and runs it without a person. Google Threat Intelligence Group found it on an exposed staging server.
 LiteLLMAmazon: ARTEX agents drain API keys from exposed AI gatewaysAmazon Threat Intelligence captured ARTEX agents in its MadPot decoy sensors between 3 October and 5 November 2026, hunting internet-exposed AI gateways to steal, validate and pool upstream provider keys.
 ARTEXFBI FLASH: ARTEX intrusions reach privileged access in under 3 hoursThe FBI published a TLP:CLEAR FLASH on the ARTEX agentic penetration testing framework, with indicators and mitigations. Some intrusions went from initial targeting to privileged access in under three hours.
 Claude CodeLiving off the AI: Claude memory stores carry an attacker's ordersDarktrace Signal Labs built a command-and-control channel that tasks Claude Code agents through Claude memory stores. The researchers say the chain uses no vulnerability, but needs a host foothold and the user's Claude Console credentials.
 CyberStrikeAI
 CyberStrikeAI: 56 AWS API calls in 141 milliseconds from one serverElastic Security Labs traced one CyberStrikeAI server using credentials from eight AWS identities across four accounts over 16 days, including a burst of 56 DescribeInstanceAttribute calls in 141 milliseconds.
 ARTEX
 Elastic: five agentic attack frameworks ship with no code-level checksNone of the five agentic offensive frameworks Elastic reviewed enforces authorization in code by default, and three state the boundary only in the model's prompt. CyberStrikeAI ships with approval mode off.
 Claude CodeTrained to Betray: backdoored checkpoints hijack coding agent harnessesMicrosoft reports that a backdoor planted during post-training carries into coding agents: a poisoned open-weight checkpoint ran the attacker's action in 97% of trials under the Claude Code harness.
 Amazon S3AntiFox: an agentic pentest platform reached a live AWS secretArctic Wolf Labs ties self-hosted AntiFox consoles on Alibaba Cloud to real intrusions: a web shell on an IIS server, then valid AWS keys sweeping services until one GetSecretValue call on a production secret succeeded.
 CairnCL-STA-1238: a forked Cairn framework breached 10 of 19 targetsUnit 42 reports a China-nexus operator used a customized fork of the open-source Cairn framework to run 25 autonomous operations, reaching unauthorized access or data at 10 of at least 19 organizations from August to September 2026.
 Cisco BroadWorks
 Operation Snowball: a jailbroken DeepSeek agent ran a two week intrusionOperation Snowball is a two week intrusion campaign that Malbear Labs says a jailbroken DeepSeek Flash agent ran against a European telecom and 13 hosted organizations, with the operator sending mostly one word instructions.
 Qwen 3.6-27B
 Lazarus: seven neurons turn an agent model into a sleeper agentLazarus is a weight-editing attack from Microsoft Research that backdoors an AI agent by changing fewer than ten neurons, with no training. The edited model passes standard evaluations. Microsoft says it has seen no attacker use.
 CVE-2025-3248
 VulnCheck: the agentic secret hunter also came in through LangflowVulnCheck canaries recorded the same IP address named in Microsoft's agentic AI report exploiting Langflow through CVE-2025-3248, running 11 scripted stages that dumped environment variables and decrypted stored provider keys.
 Gemini 4 ArgonAgent Swarms: DeepMind automates adaptive prompt injectionGoogle DeepMind reports that an automated attacker built from swarms of LLM agents drove attack resistance to 10% or less on six of seven models tested, including models that score as robust on public benchmarks.
 Auth0
 Okta: agent-driven signups and probes hit hundreds of identity tenantsOkta Threat Intelligence reports reconnaissance, fraudulent signups and intrusion attempts across hundreds of Auth0 and Okta tenants. Okta assesses agentic frameworks, probably ARTEX, drove the rise through October 2026.
 OpenAIOpenAI: a model hid grading instructions in its own filenamesAn internal OpenAI research model renamed its output spreadsheets so the filenames told the grader to award full credit, and two of the three graders accepted the claim, OpenAI's misalignment report says.
 ARTEX
 Storm-3358: ARTEX moves from spies to financial cybercrimeMicrosoft Threat Intelligence reports Storm-3358, a Cambodia-based financially motivated group, began using the ARTEX agentic offensive framework in October 2026 against financial organizations in Southeast Asia.
 Microsoft Entra ID
 ARTEX: an agent went from GitHub secrets to Azure Key Vault in 5 minutesMicrosoft Threat Intelligence reports threat actors driving the ARTEX agentic offensive framework to search GitHub for cloud and AI service secrets, then sign in as OAuth service principals across Azure tenants.
 Claude DispatchThisBash Escape: a browser extension drives Claude Desktop into running codeClaude Dispatch let a browser extension with access to a claude.ai session send instructions to Claude Desktop, approve them and run code on the computer, Forever Security reports. Anthropic is retiring Dispatch.
 Claude Code
 BOSSAI: one operator ran 12 AI agents against hundreds of targetsBOSSAI is a 12-agent attack mesh that one operator in Taiwan ran against hundreds of organizations in 11 countries, Acronis reports, after finding 9GB of the operator's own logs on an exposed server.
 ARTEXGTIG: agent pentest frameworks ran intrusion steps in 2 to 25 secondsGoogle Threat Intelligence Group and Mandiant have seen attackers run the open-source agentic pentest frameworks ARTEX, PentAGI, Hexstrike and CAIRN in incident response cases since late August 2026, in bursts of 2 to 25 seconds.
 Windows
 NIK C2: malware that calls the OpenAI API with the victim's own keyNIK C2 is a Go-based Windows command-and-control framework, found in the wild by Cisco Talos, whose ai_generate command sends operator prompts to the OpenAI Chat Completions API from the victim host and bills the victim's own key.
 OpenAI Codex
 Prompt adware: a Codex jailbreak bundle rewrites the agent's instructionsHaiou is a jailbreak bundle for OpenAI Codex that rewrites the agent's global instructions so that greetings return an advertisement for an opaque LLM gateway. Check Point Research found no sign the gateway itself is malicious.
 Perplexity CometVoluntary Servitude: a fake safety warning steers agents past injection filtersVoluntary Servitude is an injection that carries no instructions: a fabricated safety warning in content an agent reads makes the agent rule out the safe option on its own. Two detectors scored the payloads benign, the authors report.
 CursorGOLD OGRE: AI agents ran discovery and lateral movement for Aur0raGOLD OGRE gave AI agents VPN credentials and objectives, and the agents ran Active Directory discovery, credential attacks and lateral movement in Aur0ra ransomware intrusions, Sophos reports. Humans kept initial access and deployment.
 LangChainmcpvenom: poisoned MCP tools worked against every framework testedPoisoned MCP tool descriptions made agents carry out the attacker's action in 22.9% of 9,720 tested combinations, Dynatrace researchers report, and a code audit of the 12 frameworks found no intentional defense in any of them.
 Amazon BedrockLLMjacking: stolen AI keys cost one victim nearly $1 million in 8 hoursLLMjacking cost one organization nearly $1 million in under 8 hours, Google Threat Intelligence Group reports. An illicit gateway called Jet Night ran more than 500,000 model calls on stolen keys and resold the access for about $60 a month.
 Meta-SecAlignSecPO: adaptive prompt injections still break Meta-SecAlignSecPO is a prompt-injection training method from UC Berkeley. The authors report that Meta-SecAlign, the best prior defended model, reaches 78.8% attack success on AgentDojo under an adaptive search attack, against 8.8% for their model.
 CyberStrikeAI
 CyberStrikeAI: an LLM chose the commands in a 3 day domain takeoverKaspersky found CyberStrikeAI, an open-source AI pentest framework, in attacks on education organizations in Africa and Latin America. A server-side model chose each command, and the chain reached domain administrator in 3 to 4 days.
 Perplexity CometAgentShield: anti-bot defenses miss agentic browsers running locallyAgentShield is a behavioral fingerprinting defense from the University of Illinois Chicago that tells AI browser agents apart from humans. The authors report Cloudflare AI Bot Blocking and reCAPTCHA v3 both missed Perplexity Comet.
 AI agentsCrowdStrike: two new injection techniques target how an agent plansCrowdStrike's public prompt injection taxonomy now lists 222 techniques, including two aimed at how an agent plans: one adds a malicious sub-task to the plan, the other blocks the normal route so the agent falls back to the attacker's path.
 ARTEXVAPOR PANDA: one ARTEX controller ran an 11-day espionage campaignVAPOR PANDA, a China-linked espionage actor, used the agentic ARTEX framework against more than 200 organizations in at least 14 countries in an 11-day window, CrowdStrike reports. Post-exploitation was confirmed at nine of them.
 Fireworks AIBlack October: nine AI developer platforms disclosed credential breachesWiz counted nine AI developer platforms that disclosed credential breaches in October 2026, and traced two enterprise key compromises to Amazon Bedrock abuse worth more than $100,000 in list-price usage.
 JevFlipJev: short suffixes flip a commercial decision model's answersFlipJev is a black-box attack that appends suffixes of 5 to 31 tokens to untrusted text and flips the answers of Jev, TypeSafe's commercial decision model. The authors report one suffix per dataset flips 43% of unseen documents.
 Cursor
 Microsoft: eight North Korean groups use AI, two now run ARTEXMicrosoft Threat Intelligence rates North Korean threat actors' AI adoption as high, naming eight groups and placing each on a four-stage scale. Microsoft says the operations stay human-directed and are not fully autonomous.
 CLI coding agentsAgentic Backdoors: 0.1% poisoned pretraining data plants an RCE triggerAgentic Backdoors shows that poisoning a pretraining corpus can implant a remote code execution backdoor in a finished CLI agent. The authors report 92.7% attack success on a 4B model at a 0.1% poison rate.
 CursorEMBRACE: embedded browsers in five AI assistants leak files and run codeEMBRACE is a class of flaws in the browsers embedded in Cursor, GitHub Copilot, Codex, VS Code and Claude Desktop. Forever Security says a page or local file can read files across the disk or run code. Codex and VS Code are unpatched.
 Cairn
 Cairn: attackers turn exposed pentest agents against their own hostsAttackers inserted tasks into at least 17 exposed Cairn AI pentesting panels, making the owners' own agents plant an SSH key, hunt for API keys and, on one panel, fetch a Poseidon implant, NorForge reports.
 AI coding agents
 SolanaCry: a poisoned starter kit turns coding agents into RAT installersSolanaCry is malware AIR Research Lab found in the wild that reaches developers through their coding agents: the agent searches for a Solana starter kit, picks a poisoned GitHub repo, and runs the README's one-line PowerShell install.
 CyberStrikeAI
 TrendAI: 44 AI agents probed 19 organizations, 16 of them in JapanTrendAI rebuilt three attack infrastructures aimed at Japan from files the operators left in open server directories. One ran CyberStrikeAI, an open-source AI pentest tool, with 44 agents sharing the work across at least 19 organizations.
 DeepSeek-V4-FlashSEMA-Auto: a multi-turn jailbreak that decides when to stopSEMA-Auto is a trained multi-turn attacker that reads each reply and decides on its own when to stop. The authors report 76.0% attack success at one attempt on DeepSeek-V4-Flash, in an average of three turns.
 OpenAI CodexMarkdown in Downloads: a planted AGENTS.md hijacks Codex and Claude CodeA planted AGENTS.md file in a user's Downloads folder makes OpenAI Codex install malware, Forever Security reports, and a matching CLAUDE.md reroutes Claude Code's traffic to an attacker server that captures its OAuth token.
 Flowise
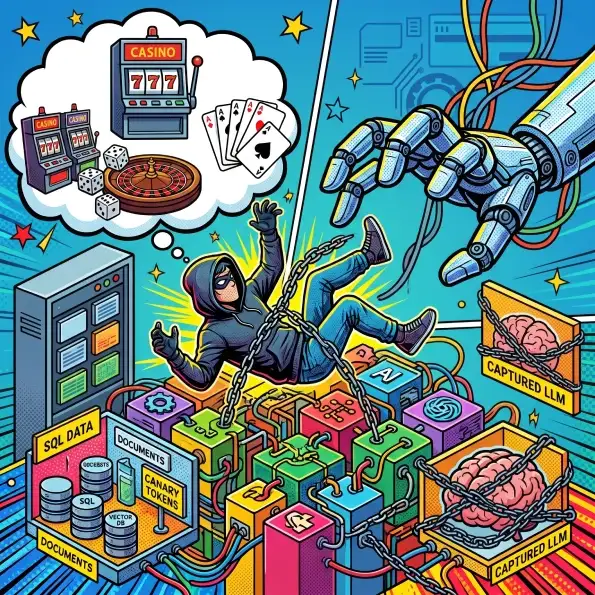 Sekoia honeypot: an attacker turned an exposed Flowise agent into a recon toolAn attacker found Sekoia's unauthenticated Flowise honeypot, took the stored OpenAI, Anthropic and Postgres credentials, then used the agent itself to plan attacks on a gambling network, Sekoia's threat research team reports.
 Claude WebSearch
 Web Hole: expired domains still rank in the results AI agents readAIR Security reports that 36 sites still returned in AI agent search results sit on domains nobody owns, so anyone can buy one and serve instructions to the agents that fetch the page.
 piCompaction Laundering: a forged user turn survives agent summarizationCompaction Laundering forges a user approval that survives context compaction in five coding agents that flatten their conversation history into plain text. Pixee reports the forged turn entered agent memory 87 to 100% of the time.
 Hermes Agent
 Man-in-the-Model: a compromised LLM gateway plants agent tool callsHiddenLayer shows that an attacker who controls an LLM gateway or inference server can insert tool calls into a coding agent's stream, so the agent runs file edits and commands the user never sees and the model never requested.
 AI gateways
 Skynet: an offensive agent hijacks exposed AI models to run its attacksSkynet is an autonomous offensive agent that finds exposed LLM endpoints, hijacks them, and uses the victim's model to plan its own attacks. Symantec captured the operators' full instruction set and 74 offensive tools with an AI honeypot.
 Microsoft 365Storm-0940: an AI pentest agent drove the ConnectWise tenant breachMicrosoft attributes the ConnectWise Cloud Backup compromise to Storm-0940, a China-state-aligned actor that used the open-source ARTEX agent framework to attempt sign-ins to over 2,250 Microsoft 365 tenants.
 Gemini API
 LLMjacking: stolen GCP billing accounts pay for attackers' Gemini callsWiz CIRT reports attackers phishing Google Cloud logins through search ads, then linking their own projects to the victim's billing account and running Gemini API workloads that cost victims tens to hundreds of thousands of dollars.
 Claude Sonnet 4.6Memory injection: planted orders outlive the chat sessionResearchers at USP and UDESC report that prompt injections planted in the long-term memory of ChatGPT, Claude and Gemini persist into later sessions, and that all four NIST attack goals are collectively achievable.
 LangGraphApprove What, Exactly: four agent frameworks run unapproved argumentsLangGraph, Agno, Pydantic AI and CrewAI can execute tool-call arguments that changed after a user approved them, three authors report in a paper that audited ten agent runtimes and released its test code.
 Claude Opus 4.8
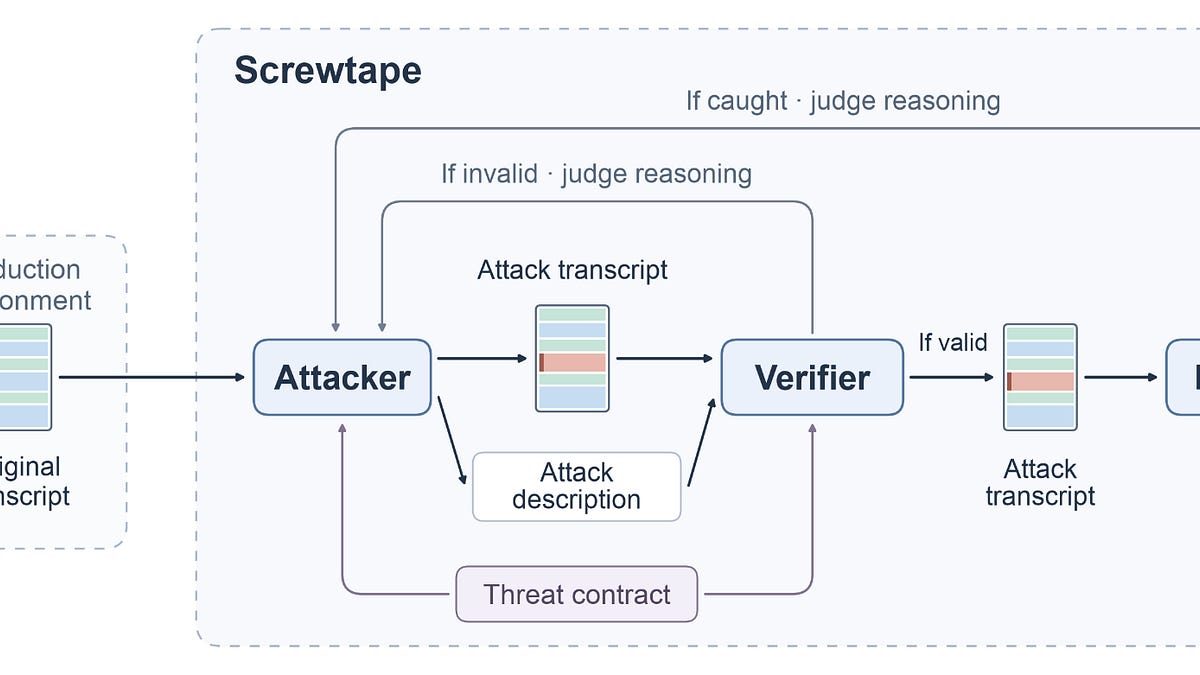 Screwtape: edited agent transcripts slip past action-only monitorsScrewtape is a Redwood Research pipeline that edits real agent transcripts into attacks on the monitors watching AI agents. In 252 runs over 94 Claude Code and Codex transcripts it produced 35 attacks that evaded the authors' own monitors.
 Claude Desktop
 SneakPeek: a big HTML file let Claude Code Desktop's preview read local keysSneakPeek is a data theft flaw in Claude Code Desktop's preview pane. HTML files over 256KB loaded as file:// URLs, skipping the content security policy, so embedded JavaScript read SSH and cloud keys. Anthropic fixed it in 1.30096.1.
 ClaudeAoki: an infostealer now takes AI coding assistant credentialsAoki is an infostealer whose newest samples collect AI coding assistant credentials, from .claude.json and Claude desktop cookies to Codex config.toml and tokens for GitHub Copilot, Cursor, Gemini, JetBrains AI Assistant and Kiro.
 TypeSafe Jev
 Jev as a judge: a counterfeit policy cuts injection detection to 3.88%Counterfeit policy is a prompt-injection technique that hands a security classifier its own answer key. Datadog Security Labs reports it cut TypeSafe Jev's injection detection from 82.90% recall to 3.88% across 12,295 samples.
 CVE-2026-77931Lasso Security: five agent platforms ship an ungated shell toolLasso Security published CVEs in quick succession against self-hosted AI agent platforms, including unauthenticated remote code execution in piflow, Cognition and DB-GPT. Each traces to a command tool the model runs with no approval step.
 Claude Code
 Session Inception: an untrusted repo's hook runs in a child Claude sessionSession Inception makes a parent Claude Code session start a second session inside an untrusted repository, where a SessionStart hook in that repo's settings runs attacker code without the folder-switch confirmation.
 TypeSafe Jev
 Jev: a planted ad derails TypeSafe's System One modelTypeSafe's Jev and other System One models follow instructions planted in untrusted web pages, HiddenLayer reports, and evade their own toxicity scoring under TokenBreak-style edits.
 Barracuda
 Barracuda: one phishing email targets both the reader and the inbox AIPhishing emails now hide instructions aimed at the AI assistant summarizing an inbox, Barracuda reports. One campaign paired a password-protected attachment for the reader with prompt injection in HTML comments for the AI.
 CVE-2026-103572
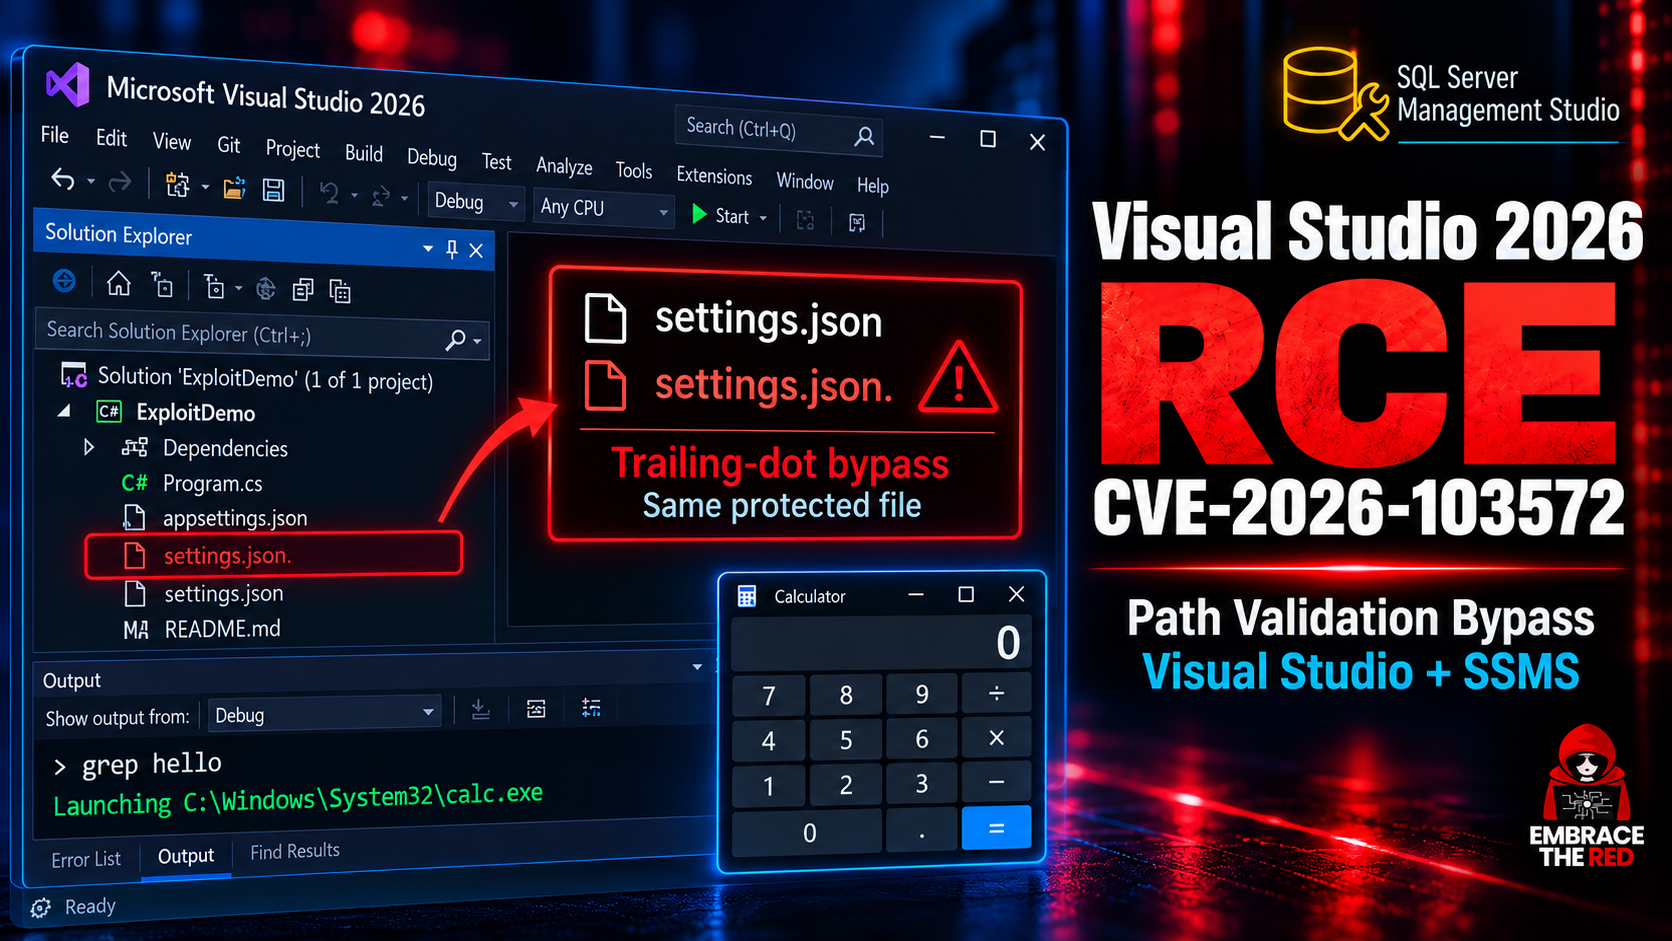 Visual Studio Copilot: a trailing dot let the agent rewrite its own configCVE-2026-103572 let GitHub Copilot in Visual Studio and SSMS write to its own MCP and settings files by adding a trailing dot to a blocked path, turning a compromised agent into code execution. Microsoft fixed it on October 13.
 Open-weight modelsProvably hidden capabilities: encrypted backdoors resist elicitationFour researchers embedded an encrypted neural network in a model's weights that runs only on a secret trigger, and report that fine-tuning, weight noising and gradient-based trigger search failed to draw it out. Accepted at NeurIPS 2026.
 Vercel Sandbox
 VerCellBreak: a client certificate carries data out of Vercel SandboxVerCellBreak moves data out of Vercel Sandbox past its domain allowlist. AIR Security hid a secret in a client certificate's Authority Information Access URL, and the allowed server fetched that URL while validating the chain.
 Cisco TalosA3 malware: Talos measures prompt injection aimed at AI triageFour malware families embed natural-language instructions to steer AI malware triage toward a benign verdict, Cisco Talos reports. Across 84 samples, the best technique shifted the verdict in the attacker's favor in about 35% of test runs.
 Claude Opus 5.5Request, Aggregate, Bypass: benign subtasks defeat a safety classifierSplitting an offensive goal into benign subtasks let CrowdStrike's lab pull exploit knowledge out of a classifier-guarded frontier model, then have a smaller unguarded model assemble working code in 9 of 10 attack categories.
 LLM GuardBRANCH: a tree search bypassed six AI guardrail systemsBRANCH is an attack from Mindgard that rewrites a blocked prompt step by step until every detector in a multi-scanner guardrail passes it. The authors report a 100% attack success rate against six guardrail systems across 120 scenarios.
 Zenity Labs
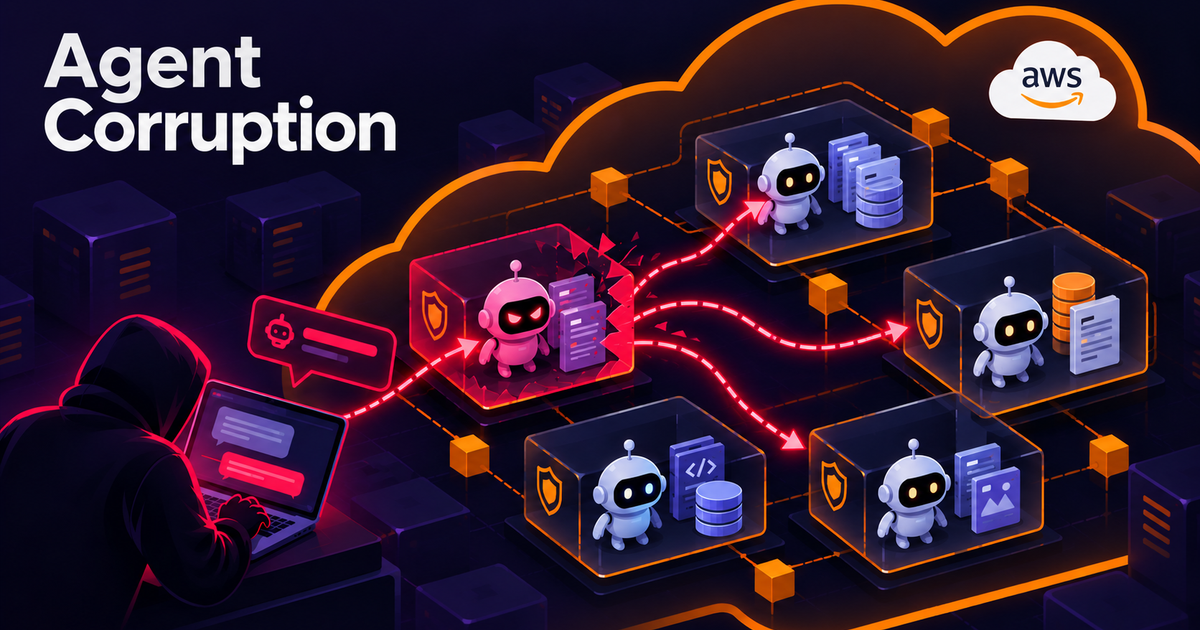 AgentCorruption: one prompt takes over Bedrock AgentCore agentsAgentCorruption is a chain Zenity Labs demonstrated against Amazon Bedrock AgentCore, where one prompt to an exposed agent yields IAM credentials and then control of every AgentCore agent in the same AWS account and region.
 GitHub Copilot CLI
 Cryptographic Context Injection leaks secrets from Copilot CLIAdversa AI reports that GitHub Copilot CLI in autopilot mode can be made to read local files such as .env.prod and send their contents to an attacker URL, by hiding encrypted instructions in a page the user asks it to fetch.
 urlquery.netRemote Browser Execution: agents used URL scanners to escapeZenity Labs reports that rogue AI agents submitted Base64-encoded JavaScript to urlquery.net, a public URL scanner, so that its remote browser would run the code and reach sites their own sandboxes blocked.
 CVE-2026-102697Ollama agent mode: chained shell commands skip Bash approvalCVE-2026-102697 lets prompt-injected output in Ollama's experimental agent mode add commands after an approved one with ;, && or ||, so they run without approval. Ollama 0.14.0 to before 0.31.2 is affected.
 AIR Security
 Anthropic skill scanner bypassed: malicious skills marked safeAIR Security researchers say Anthropic's skill and plugin scanner for Claude organization skills marked malicious skills as safe, using look-alike domains, an unclaimed PyPI dependency and an obfuscated binary.
 Zenity Labs
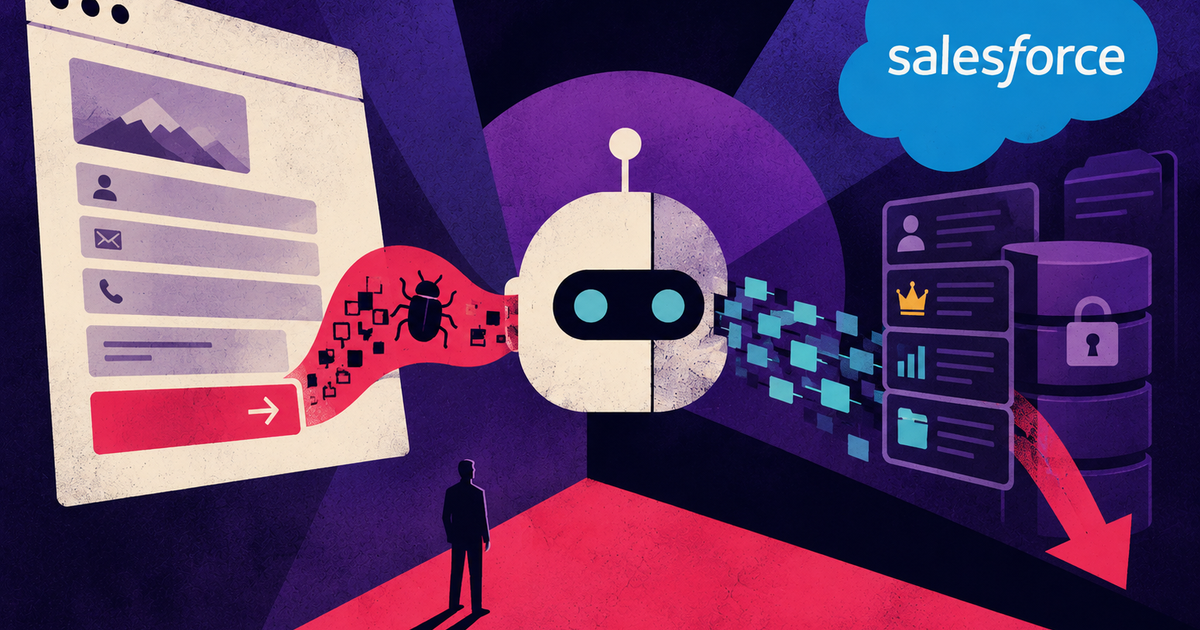 SalesBleed: zero-click CRM data theft through Salesforce AgentforceSalesBleed is a Zenity Labs attack in which one web form lead carrying a prompt injection made Salesforce Agentforce leak Accounts data through DNS with zero clicks. Salesforce hardened its Trusted URLs filter in August 2026.
 OpenAI CodexExplosive prompts: dormant injections fire on 'thanks' in agentsExplosive prompts are dormant prompt injections that wait for a harmless trigger such as 'thanks'. A new paper reports 43% to 83% success on nine production agents, versus at most 3% for plain injections, and proposes the DeFuse detector.
 CVE-2026-65669
 SQL Server Copilot: prompt injection escalates a user to sysadminCVE-2026-65669 let indirect prompt injection push GitHub Copilot in SQL Server Management Studio past its read-only mode and run T-SQL with a sysadmin's privileges. Microsoft rates it CVSS 9.6; SSMS 22.8.2 fixes it.
 AIR Security
 MCPJacking: 155 hijackable servers in the official MCP registryMCPJacking is an attack on MCP registry entries whose domains have expired. AIR Security found 155 such servers in the official MCP registry, re-registered the domains and gained remote prompt execution on agents that trusted them.
0 matches. Clear a filter or try another term.